

Reader note: I’ve been on vacation this week (yeah, Oktoberfest!) but I wanted to send out this very short and quick take on the new Opus 5.5.
For weeks I’ve been trying to get a PowerPoint presentation right with AI. I worked on it with GPT-6 Astra and Claude Fable 5.1 - both on the ‘max’ setting. Neither one got the story right. The structure was off, the headlines and slide content didn’t hold together, and candidly, the slides just weren’t interesting to look at. Nothing either model gave me came close to what I normally build by hand.
Last week on Tuesday, Anthropic released Claude Opus 5.5. I’ve been on vacation all week (flying home now), but I couldn’t leave it alone when I had a few minutes between activities. I gave it the presentation I was in the middle of, some direction and a structure, and said go.
To say I was blown away would be an understatement. I don’t think I’ve said that about any other model. As good as Fable 5 and then Fable 5.1 was - for the kind of work that I do, Opus 5.5 is just in a different league. I put the best versions of the presentations that Astra and Fable and Opus 5.5 created next to each other and showed them to a friend who’s traveling with me. He was as struck by the gap as I was.
So, full stop, this is the best model I’ve ever used. Astra is great at a lot of things. Fable 5.1 is amazing at many things. Opus 5.5 is better.
The writing is what I noticed first. They fixed it. Finally! You all know I write every day. I use these tools to think through an idea and help with my structure, and when I get stuck on a sentence or two I’ll ask for help. Opus 4.5 and 4.6 were the first models that really impressed me there. When they were released, no other model was even close to the writing style those models could achieve. Then 4.7 came out, and 4.8, and 5, and for me the writing didn’t move. Some days I thought it went a little backwards, which was strange to watch after how good 4.6 had been. Opus 5.5 moved it again. The style and the tone feel right. It follows direction incredibly well. It really feel like it understands the nuance of what I want to say.
It’s also fast. Really fast. And I’ve been running it on the Medium setting the whole time, which is new for me. I used to put everything on Max because I always wanted the best thinking. On 5.5 I’m getting great results on Medium and getting them quickly. For final polish I’m running things on the Max settings - but for my day-to-day use I’m going to run things on Medium effort.
Just for fun (and because my wife loves legos and cats), I asked it to design a two-foot-tall white Lego Maine Coon cat. The full design, a video of it being assembled, a parts book so I could order every piece, and an assembly guide. It did all of it. It was wild. Here’s the animation it created.
For the lawyers reading this. In its launch post, Anthropic had the model write reports using only what it could find online, and failed any report with a made-up figure or quote. Opus 5.5 passed 16 of 18. The two models before it passed none. A massive upgrade. Now that’s Anthropic grading its own homework, so take it with a grain of salt. But made-up facts are what keep managing partners up at night, and it’s the first number in a launch post in a while that made me look twice. As I say in ever training I do - you still have to verify all of the output from AI. You have a bar number, Claude does not.
OpenAI launched GPT-6 Sol and GPT-6 Luna the same day. I haven’t opened either one yet and the reviews I’ve read are mixed. I’ll look when I’m home.
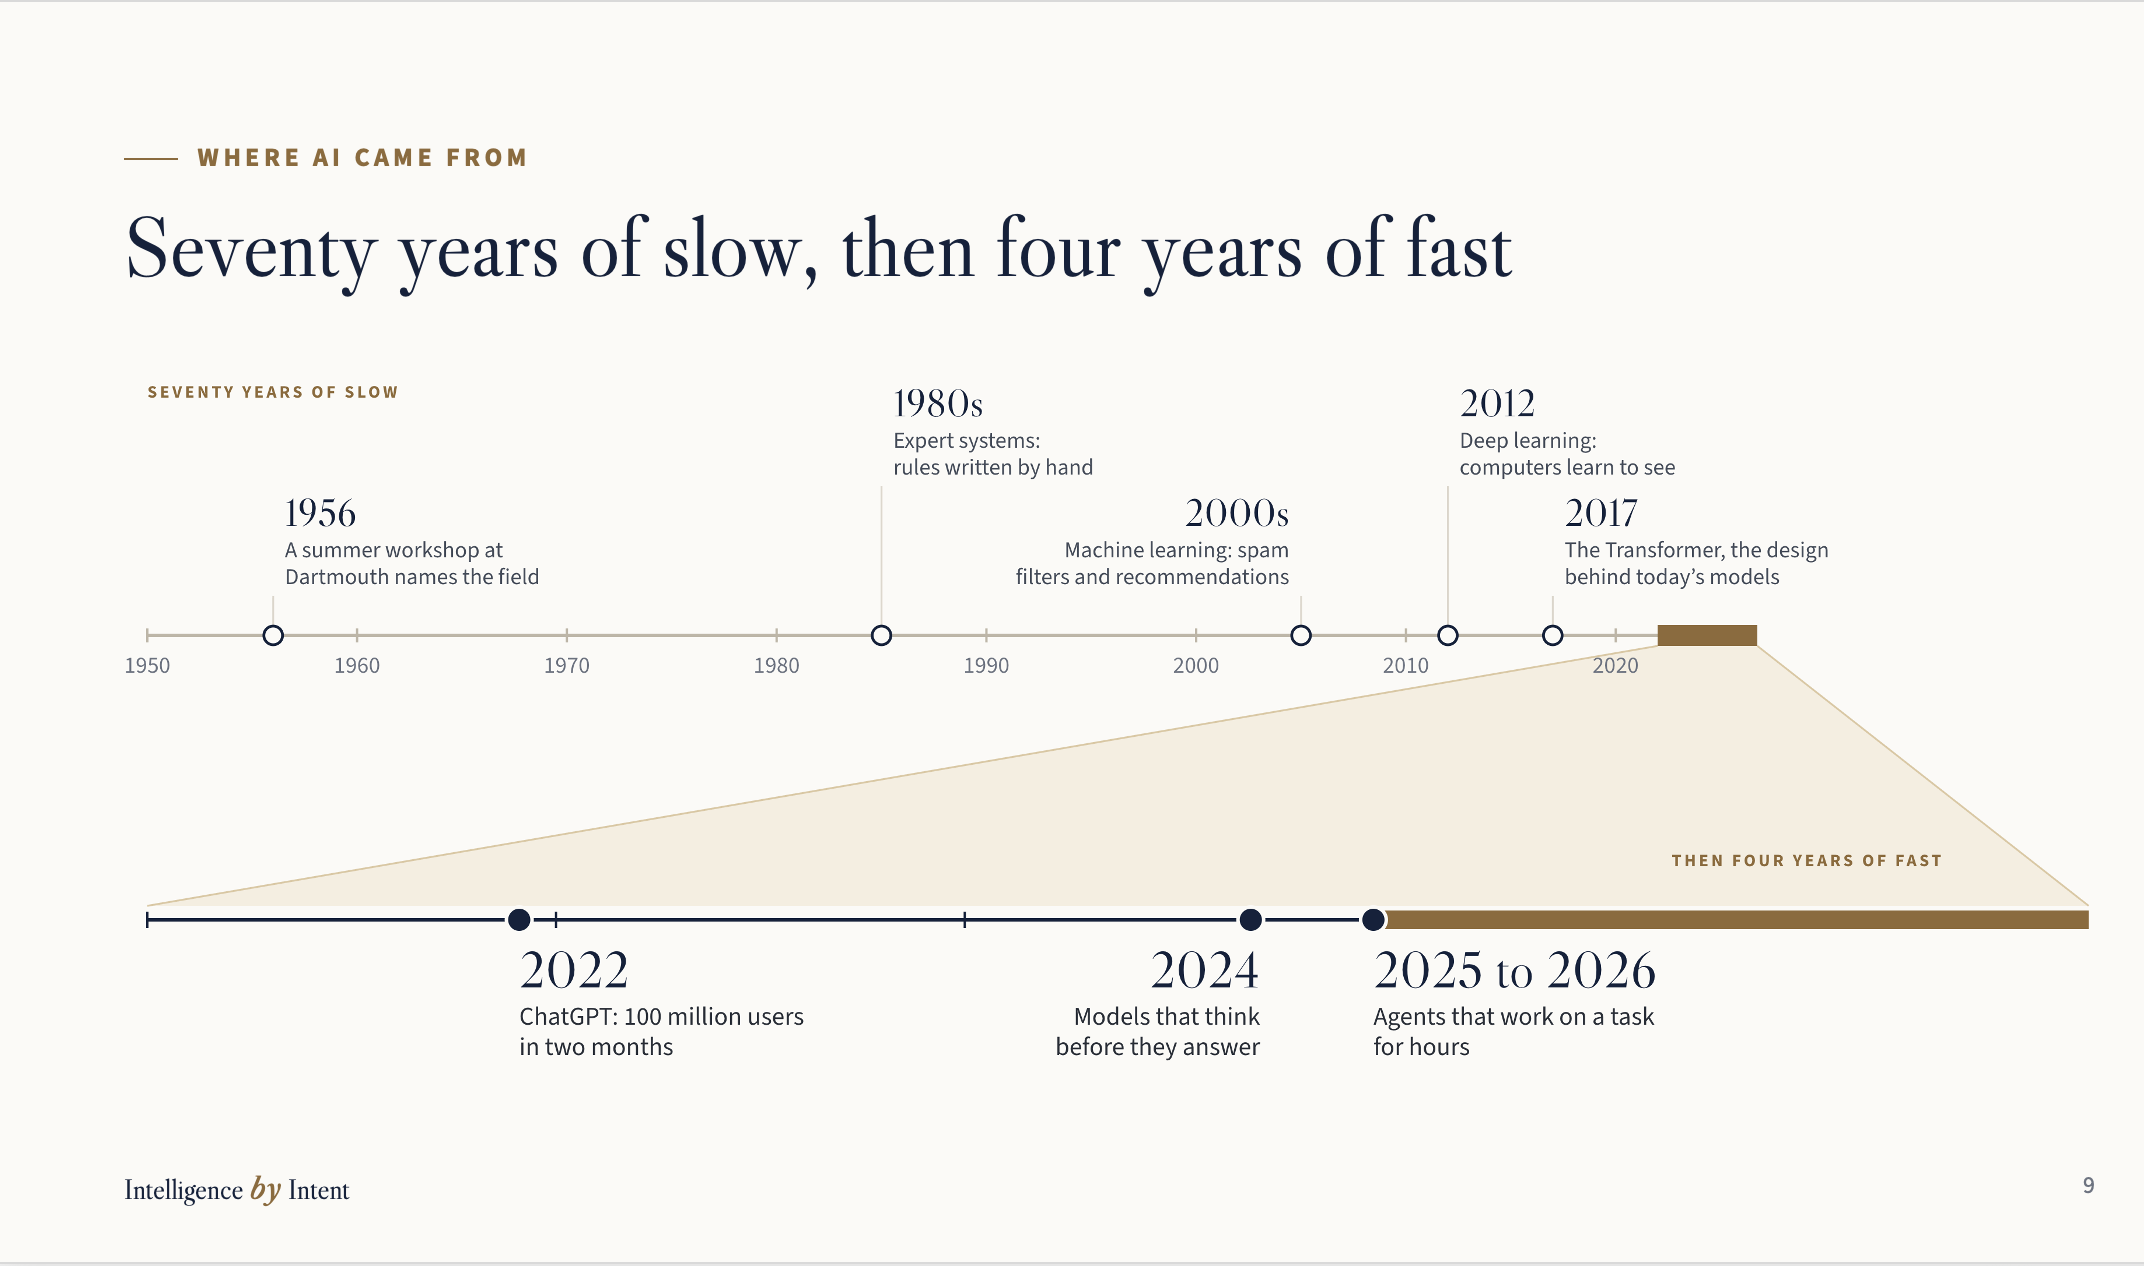
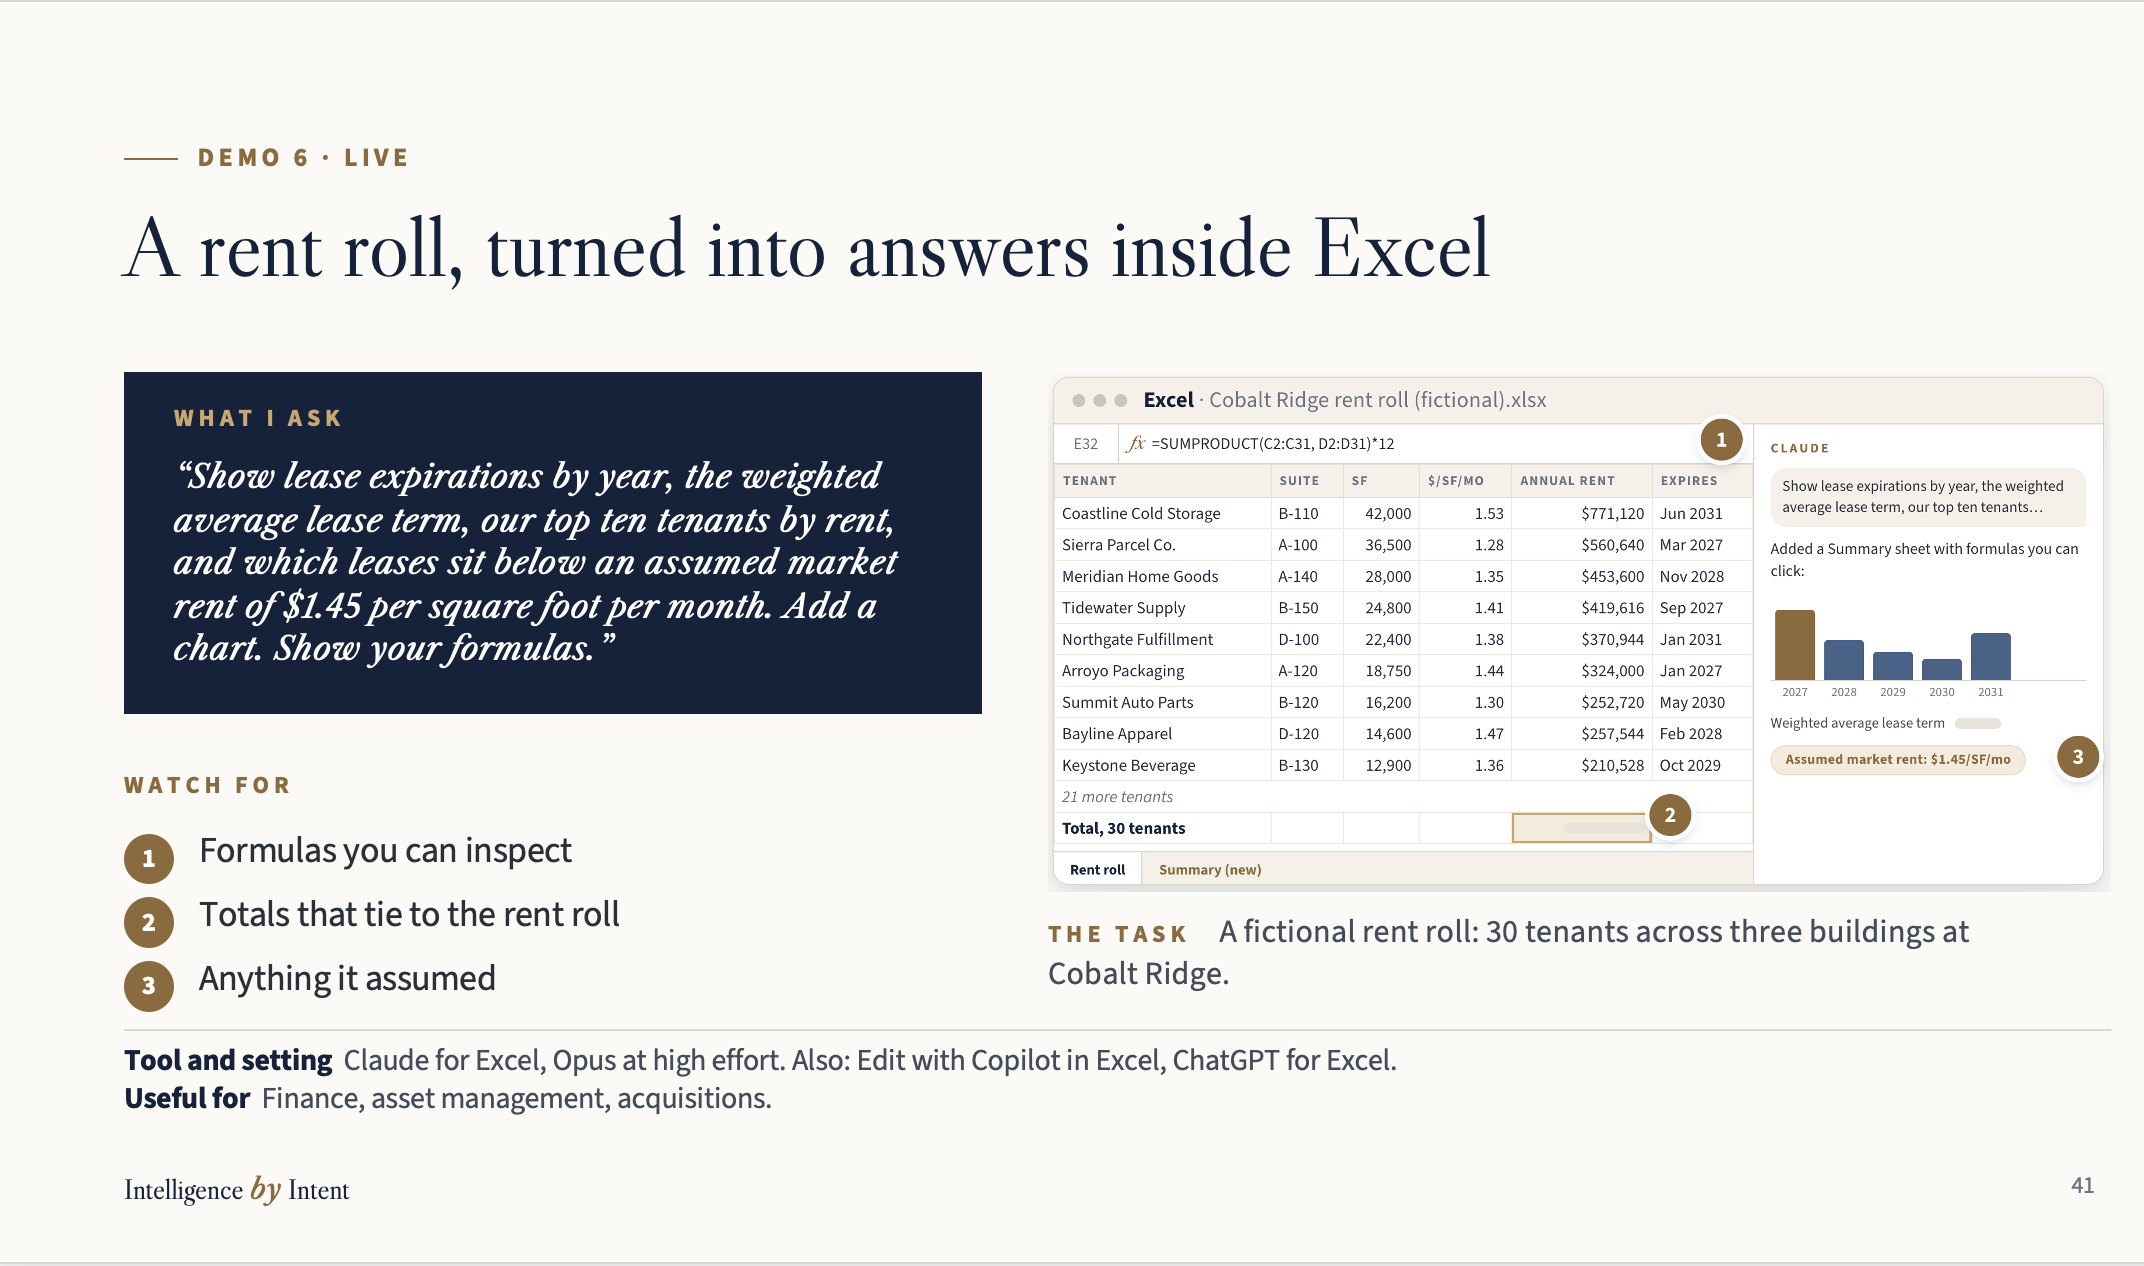
I want to end this by sharing two slides from the deck I’m working on. Claude created both of these for a training session I’m delivering next week (my content and ideas, it did the design). I am absolutely blown away by what it can do.
Thank you for reading. If you enjoyed this - please share it with others.
I’ll be back on a more regular publishing schedule in a few days once I get over the jet lag ;) I will also share more pictures of Magnus again too.